
Smarter’s Ownership Model: One Base Class for Owning, Sharing and Tracking AI Resources

An AI platform is mostly a catalog of resources that people make, such as chatbots, the plugins and tools they call, the database and api connections those tools use, the secrets those connections need, guardrails, MCP clients, LLM providers, vector stores and api keys. In a platform used by one person, a resource is just a row. In a platform used by many organizations, each with many people, every one of those rows raises the same questions. Who owns it? Who else may see it? Who may change it? Who pays when it runs? And how does the rest of the platform find it again, fast, from a manifest, a url, a budget or a log?
Those questions are easy to answer once. They are hard to answer the same way in every model of a growing codebase, and an inconsistent answer isn’t a cosmetic bug. If one model forgets the ownership filter that the other models apply, a Secret from one company shows up in another company’s list. The consequences of AI resource ownership are a data leak, a bill sent to the wrong customer, or a chatbot that a stranger can rewrite.
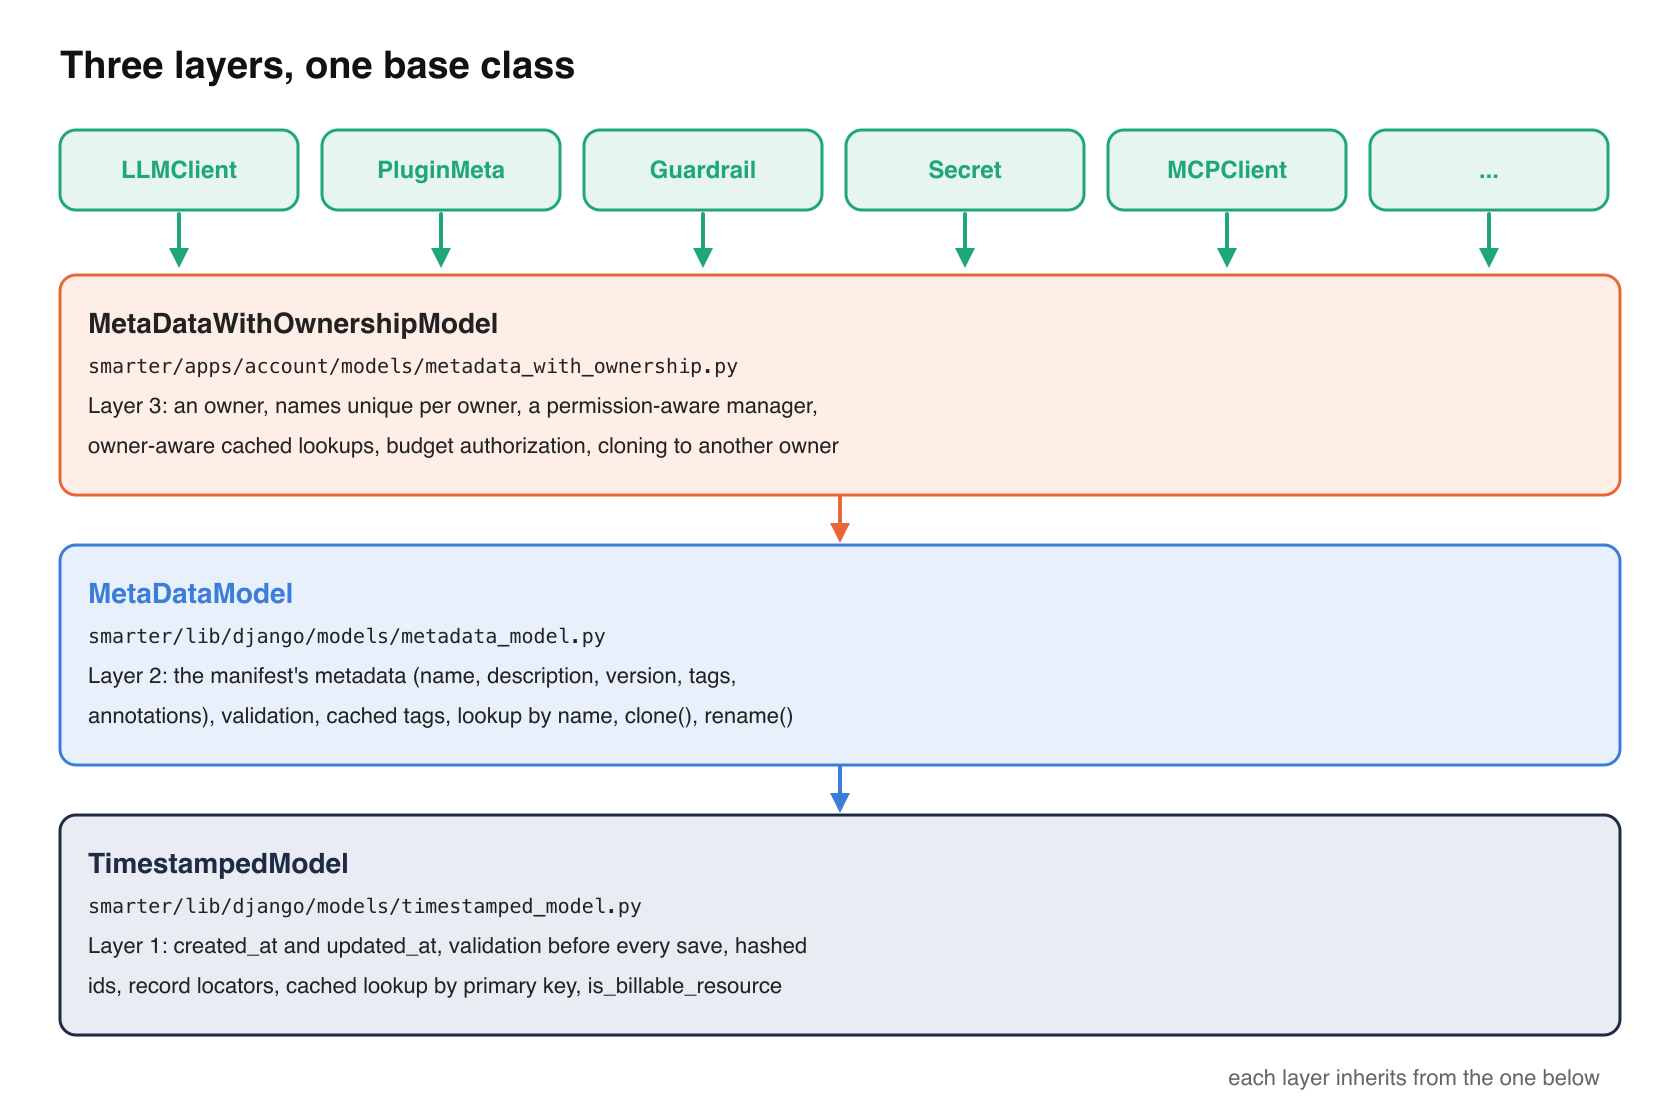
Smarter answers all of them in one place, MetaDataWithOwnershipModel, an abstract Django model that nearly every AI resource in Smarter inherits from. It sits on top of two more abstract models, MetaDataModel and TimestampedModel, and each of the three adds one layer. The first adds global identity and caching, the second the manifest’s metadata, and the third ownership and sharing. This post walks through the three layers, the problems each one solves, and the code.
The problem space
Smarter’s resources are declared in YAML manifests and applied through a cli or a REST api, so every resource has the same outer shape, made of a kind, a metadata block with its name, description, version, tags and annotations, and a spec. The database has to hold that shape, and it has to answer five kinds of question about every row.
- Ownership. Every resource belongs to someone, who may change it, delete it and pay for it. That someone isn’t just a user. A person can belong to several organizations, and a chatbot that they build at work belongs to their employer’s account, not to the person.
- Sharing. Teammates need to see and use each other’s resources, so a team can build one chatbot from another’s plugins. The platform itself ships resources that everyone uses, such as built-in Guardrails, and nobody should have to copy them into their own account to use them.
- Names. Manifests refer to each other by name. An LLMClient lists its plugins, a plugin names its connection, a connection names its Secret. Two people will both call something
support, and both have to work. - Identity across the platform. Budgets, charges, resource locks, the web console’s urls and the dependency tree of a chatbot all need to point at a resource of any kind, with one value, without knowing which table it’s in.
- Speed. Most of these lookups happen on every request. Resolving a chatbot’s owner, its account and its tags for each prompt can’t cost several database queries each time.
Django has good answers to parts of this. django.contrib.auth permissions are per model, not per row. They say whether a user may change LLMClients, not which ones. django-guardian adds per-object permissions, as a table of grants, one row for each object and each user or group it’s shared with. That is flexible, but the table grows with users times objects, and every new resource needs its grants written. Schema-per-tenant packages such as django-tenants separate organizations completely, which is the opposite of what platform-wide built-ins need. Smarter needs something in between, with organizations that are isolated by default, sharing inside an organization without grant rows, and a platform account whose resources everyone can read.
Three layers, one base class
| Class | Where | What it adds |
|---|---|---|
TimestampedModel | smarter/lib/django/models/timestamped_model.py | Indexed created_at and updated_at, validation before every save, hashed ids, record locators, cached lookup by primary key, and whether a row is billable |
MetaDataModel | smarter/lib/django/models/metadata_model.py | The manifest’s metadata (name, description, version, tags and annotations), with validation, cached tags, cached lookup by name, clone() and rename() |
MetaDataWithOwnershipModel | smarter/apps/account/models/metadata_with_ownership.py | An owner, names unique per owner, a permission-aware manager, owner-aware cached lookups, budget authorization, and cloning to another owner |
A new resource kind gets all of it by inheriting from the last one.
class Guardrail(MetaDataWithOwnershipModel):
    """A Smarter Guardrail."""
The rest of this post goes through the layers from the bottom up.
Layer 1 is TimestampedModel, so that every row can be found from anywhere
Validate before every save
TimestampedModel overrides save() to call validate() first, and to refuse the save with an error that names the model, the arguments and the field values if validation fails. Subclasses add their own rules by overriding validate() and calling super(). Because it is in save(), the rules apply to every path that writes a row, including the manifest brokers, the web console, the Django admin, management commands and tests. A Django model’s full_clean() only runs when someone remembers to call it.
One string that identifies any row of any kind
The most far-reaching thing in TimestampedModel is two short properties.
@cached_property
def hashed_id(self) -> str:
    id_value = int(self.id) + self.HASH_FLOOR
    encoded = str(base64.urlsafe_b64encode(str(id_value).encode()).decode().rstrip("="))
    return f"{self.HASH_PREFIX}{encoded}{self.HASH_SUFFIX}"

@cached_property
def record_locator(self) -> str:
    prefix = str(self.__class__.__name__).lower()
    return f"{prefix}-{self.hashed_id}"
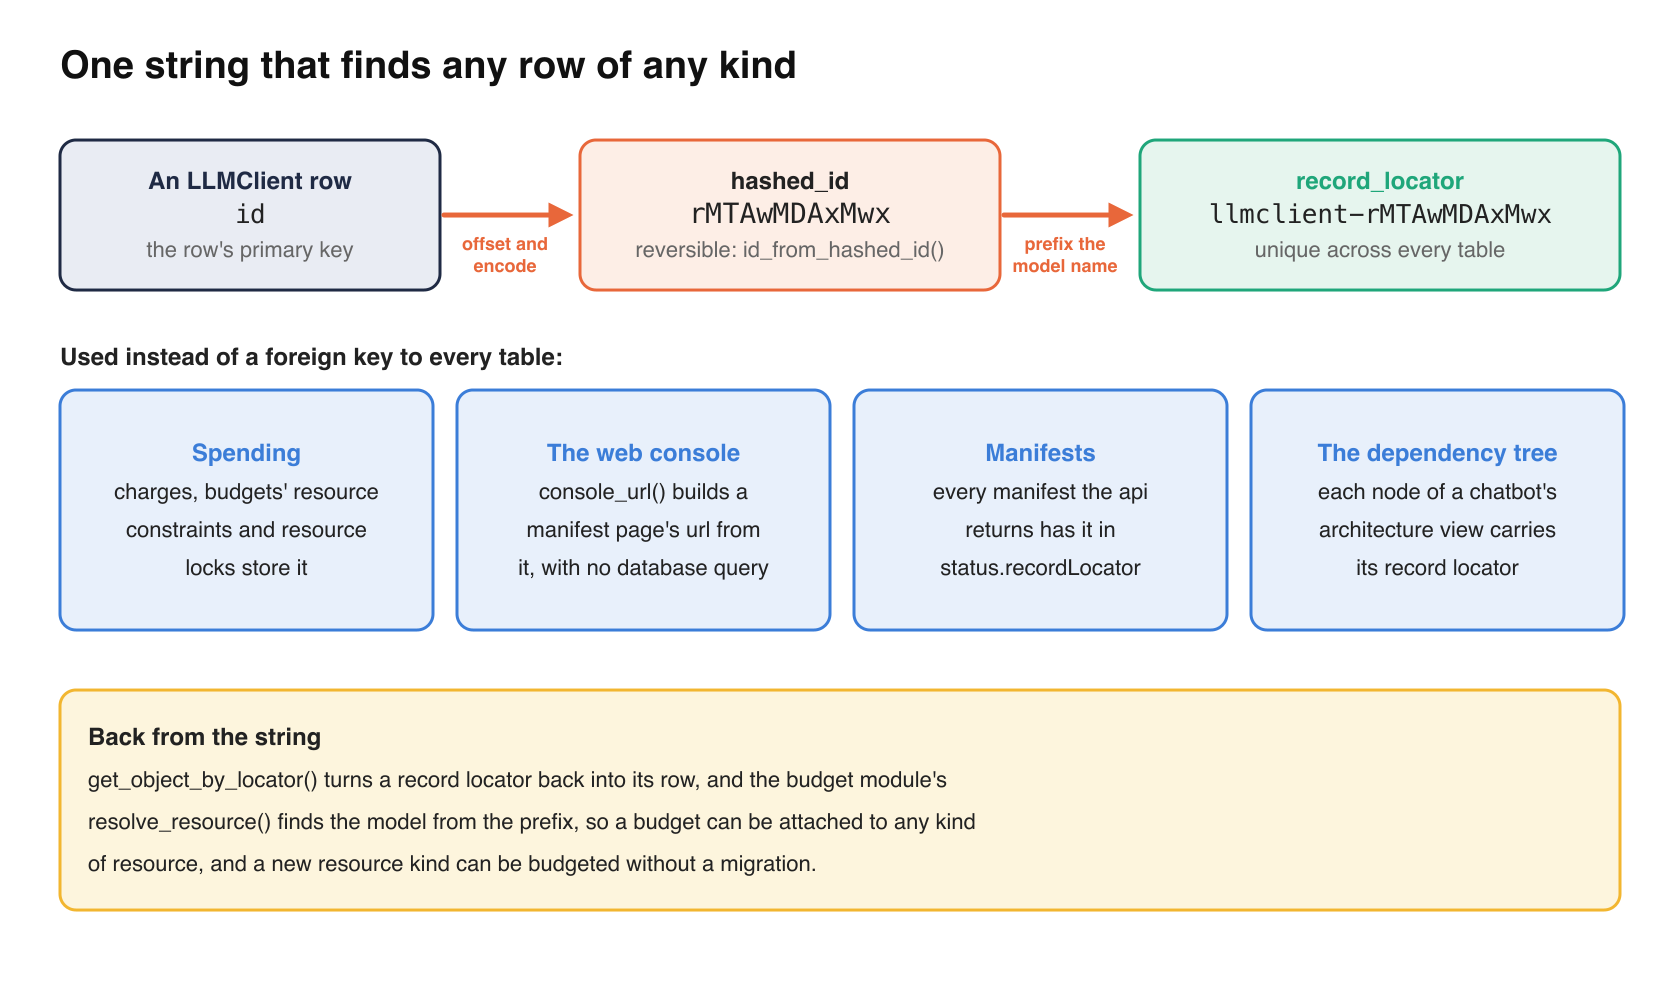
A hashed id such as rMTAwMDAxMwx is the row’s id, offset and encoded. It isn’t encryption, and it isn’t meant to be. It keeps sequential ids out of urls and is reversible with id_from_hashed_id(). A record locator adds the model’s name, such as llmclient-rMTAwMDAxMwx, which makes it unique across every table in the platform. get_object_by_locator() turns it back into the row, and the budget module’s resolve_resource() finds the model from the prefix, so a record locator alone is enough to find any resource.
That one string is how the rest of the platform refers to resources without a foreign key to every table.
- Spending. A charge, a budget’s resource constraint and a resource lock each store a record locator, so a budget can be attached to an LLMClient, a plugin, a connection, a user or a whole account, and a new resource kind can be budgeted without a migration.
- The web console.
console_url()insmarter/lib/manifest/record_locator.pybuilds the url of a resource’s manifest page from its record locator, without a database query. - Manifests. Every manifest that the api returns has its resource’s record locator in
status.recordLocator. - The dependency tree. A chatbot’s architecture view lists its Provider, its plugins, their connections and those connections’ Secrets, and each node carries its record locator.
A cached lookup that every model inherits
TimestampedModel.get_cached_object(pk=...) and get_cached_objects() are the start of a chain of cached lookups that each layer extends. They are built on @cache_results(), which the post on Smarter’s caching decorator explains in detail, and they refuse to run on an abstract class. The cached function is defined inside the classmethod, so it takes a class_name argument whose only purpose is to be part of the cache key, which keeps LLMClient 5 and Guardrail 5 from sharing an entry.
Billable is a property of the kind
is_billable_resource is False on TimestampedModel, and the kinds that spend money (LLMClients, plugins, connections, providers, proxies, prompts and vector stores) override it to return True. Layer 3 uses it to decide whether a budget check is needed at all.
Layer 2 is MetaDataModel, so that the database speaks manifest
Every manifest has the same metadata block, validated by a Pydantic model on the way in.
metadata:
  name: stackademy_sql
  description: Answers questions about Stackademy's courses.
  version: 1.0.0
  tags:
    - education
  annotations:
    - smarter.sh/owner-team: curriculum
MetaDataModel gives every resource the same five columns, name, description, version, a TaggableManager from django-taggit, and annotations as JSON. A broker copies the manifest’s metadata into them on apply, and copies them back out on describe, so a resource round-trips between YAML and the database without any kind-specific code for its metadata.
Validate the metadata where it’s stored
The model validates what it stores, not just what a manifest sends. validate() refuses a version that isn’t MAJOR.MINOR.PATCH, and because TimestampedModel.save() calls it, a row created in the Django admin or a management command is held to the same rule as one applied from a manifest. The name field’s validators, snake case and no spaces, run in full_clean(), which rename() and clone() call before they save.
Cache the tags, and invalidate them on m2m_changed
Tags are a many-to-many relation, so reading them is a query. tags_list caches them twice, in the instance, with @cached_property, and in Redis, with @cache_results(), so they outlive the instance. Changing a resource’s tags doesn’t save the resource, so post_save never fires, but Django’s m2m_changed does, so one receiver clears both caches for any MetaDataModel whose tags are added, removed or cleared.
@receiver(m2m_changed)
def tags_changed(sender, instance, action, **kwargs):
    """Invalidate tags_list when the tags of a MetaDataModel instance change."""
    if action in ("post_add", "post_remove", "post_clear") and isinstance(instance, MetaDataModel) and instance.pk:
        instance.__dict__.pop("tags_list", None)
        _get_tags_by_model_and_pk.invalidate(instance._meta.label, instance.pk)
MetaDataModel also adds lookup by name to the cached lookups, rename(), a clone() that copies the metadata, and rfc1034_compliant_name, which turns stackademy_sql into stackademy-sql for a deployed chatbot’s hostname.
Layer 3 is MetaDataWithOwnershipModel, for ownership and sharing
The owner is a UserProfile, not a User
The whole ownership model is one foreign key and one constraint.
class MetaDataWithOwnershipModel(MetaDataModel):

    class Meta:
        abstract = True
        unique_together = (
            "user_profile",
            "name",
        )

    objects: MetaDataWithOwnershipModelManager = MetaDataWithOwnershipModelManager()

    user_profile = models.ForeignKey(UserProfile, on_delete=models.CASCADE)
A UserProfile is a user’s membership in one account. It’s unique on (user, account), and neither can change after it’s created. A person who belongs to two organizations has two profiles, and the web console’s user menu chooses which one they’re working as. Making the profile the owner, rather than the user, answers several questions at once.
- Whose is it? The resource belongs to that person, in that account. Leaving one organization doesn’t take their resources out of another.
- Who pays? Charges are recorded per profile, and a budget attached to a user applies to each of their profiles.
- Which names collide? Names are unique per owner, not per table, so two people can each have a chatbot called
support, and one person can have asupportin each of their accounts.
Share by rule, not by grant
Sharing in Smarter has no grant table. Who may read a resource follows from who owns it. This is the core of with_read_permission_for(), trimmed.
def _get_for_user_profile(user_profile: UserProfile) -> models.QuerySet[_MT]:
    if user_profile.user.is_superuser:
        return self.all()
    return self.filter(
        models.Q(user_profile__account=smarter_cached_objects.smarter_account)
        | models.Q(user_profile__account=user_profile.account)
    )

qs = self.none()
for request_user_profile in UserProfile.get_cached_objects(user=user):
    qs = qs | _get_for_user_profile(request_user_profile)
return qs.distinct()
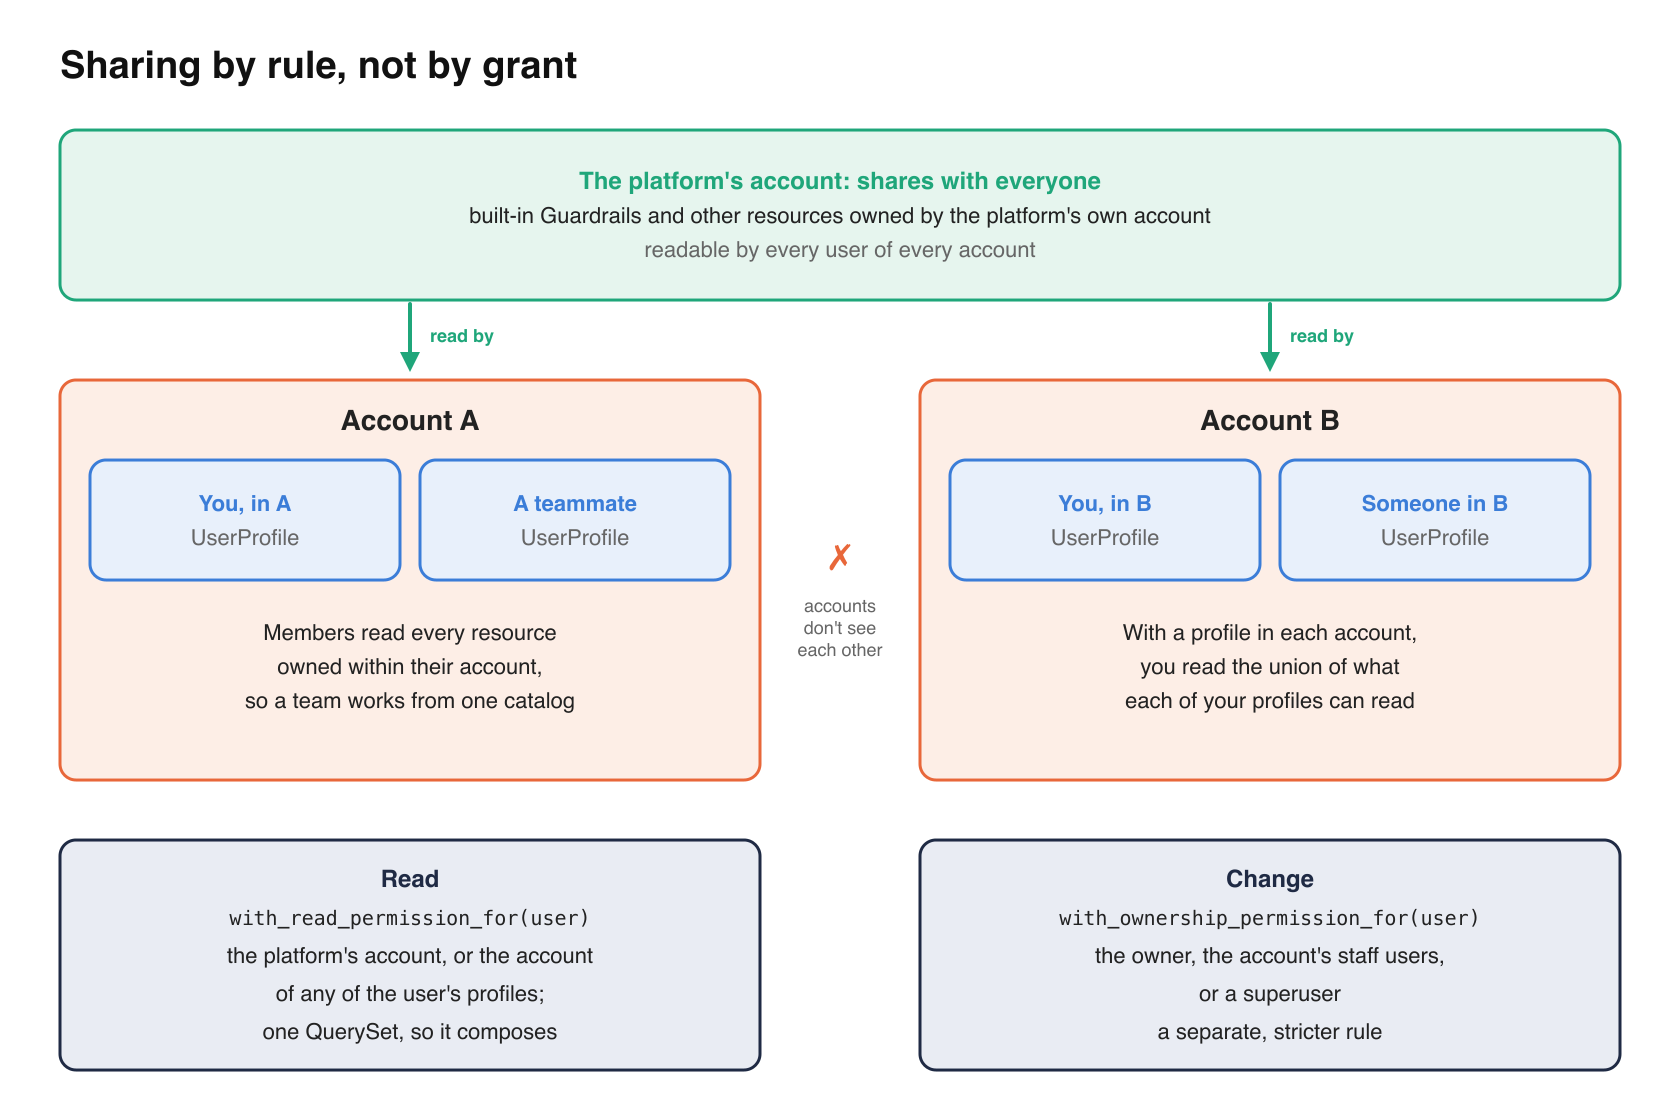
Two rules cover everything.
- An account shares with its members. Everyone in an account can read the resources owned within it, so a team works from one catalog.
- The platform shares with everyone. Resources owned by the platform’s own account, such as the built-in Guardrails, are readable by every user of every account.
Accounts don’t see each other’s resources, and nobody writes a grant. A person in several accounts reads the union of what each of their profiles can read. Because the result is a QuerySet rather than a list of ids, it composes with everything else. .filter(), .order_by(), pagination and select_related() all apply to it, and it’s one SQL query with a join to the owner’s profile.
Changing a resource is a separate, stricter rule, with_ownership_permission_for(). The owner may change their own resources, an account’s staff users may change any resource owned within their account, and superusers may change anything. Two more methods name the web console’s tabs. owned_by() is what a user owns, and shared_with() is what they may read but don’t own. The shared list view calls these three methods and nothing else, which is why the “Owned” and “Shared” tabs mean the same thing on every list page in the console.
A manager that never loses the permission methods
A custom QuerySet’s methods are easy to lose, if not at run time then in your editor. MetaDataWithOwnershipModelManager overrides get_queryset() to return a SmarterQuerySetWithPermissions, which is enough for Django to return one from every manager method at run time. But django-stubs types a manager’s filter() as returning a plain QuerySet, so to a type checker, LLMClient.objects.filter(...).with_read_permission_for(user) calls a method that doesn’t exist. So the manager also overrides every method that returns a queryset (filter, exclude, select_related, prefetch_related, annotate, order_by, union, and the rest) with the permission-aware return type, generic in the model. The permission filter is always one method call away, wherever a query starts, and the type checker agrees.
Read by name, write only your own
Sharing makes names ambiguous. The name support might be your own Guardrail, a teammate’s, or the platform’s. Smarter’s manifest brokers settle it with a simple rule. apply and delete act only on the caller’s own resource with that name, found by owner and name. describe finds the caller’s own resource first, and otherwise the oldest one of that name that they may read, which is what readable_by_name() in the abstract broker does.
if owned is not None:
    return owned
return (
    model_class.objects.with_read_permission_for(self.user_profile.user)
    .filter(name=name)
    .order_by("pk")
    .first()
)
So smarter get guardrails lists the built-in Guardrails alongside your own, smarter describe guardrail <name> shows any of them, and smarter apply of a Guardrail with a built-in’s name creates your own, rather than changing everyone’s.
The same rule shapes the dependency tree. A node that the user may not read keeps its kind and record locator, so the tree still shows that something is there, but not its name, owner or url, or anything that it uses in turn.
Customize a shared resource by cloning it
If you can’t change a shared resource, you can copy it. clone() copies every concrete field of a resource into a new row, optionally for a new owner, and finds a free name (support (clone), support (clone 1), …) if you don’t give one. The web console’s Clone action reads the source with with_read_permission_for(), so you can clone anything you can see, and then clones it into your own profile.
guardrail = Guardrail.objects.with_read_permission_for(self.user_profile.user).get(id=guardrail_id)
cloned_guardrail = guardrail.clone(new_name=new_name, user_profile=self.user_profile)
That’s how a team starts from a built-in Guardrail and tunes it, without asking anyone for permission and without affecting anyone else.
Cache lookups by every way a resource is named
A resource is looked up four ways, and get_cached_object() caches each one separately, by primary key, by session key (for the models that have one), by name and owner, and by name and account. Each cached query joins the owner chain and prefetches the tags.
cls.objects.prefetch_related("tags")
    .select_related("user_profile", "user_profile__account", "user_profile__user")
    .get(name=name, user_profile_id=user_profile_id)
So a cached LLMClient arrives with its owner, their account and their user, and checking who owns it or which account to charge costs no more queries. The cache keys take ids, not model instances, as @cache_results() requires. get_cached_objects(user_profile=...) caches each owner’s list of resources the same way.
When a resource kind that inherits directly from MetaDataWithOwnershipModel is saved, the base class invalidates its cached lookups by primary key, by name and owner, and by name and account, and its owner’s list, so an edited resource isn’t served stale by any of them. A kind with an intermediate base class, such as the connections, and a model with its own caching module, invalidates its own entries.
Check the budget before spending, not before reading
authorize() is the last line of defense against overspending.
def authorize(self) -> None:
    if not self.is_billable_resource:
        return None
    charge_authorization(self.record_locator, self.__class__.__name__)
charge_authorization() looks up the resource’s record locator in the budgets’ resource locks, a cached check because it runs on every billable request, and raises SmarterBudgetExceeded if a lock forbids the charge. A plugin calls it on its connection just before it queries the database. Lookups and readiness checks deliberately don’t call it, so a resource whose budget is exhausted can still be viewed, edited and fixed. It just can’t spend.
Other technical challenges
- Deleting an owner.
on_delete=models.CASCADEfrom the profile means that removing someone from an account removes their resources in it, and nothing is left without an owner. That’s the right default for personal resources. An account that wants to keep them clones them to another owner first. - Abstract classes can’t be looked up. Every cached lookup refuses to run on an abstract model, with
NotImplementedError, rather than build a cache key for a class that has no table. - Not everything is owned. Some kinds don’t fit the model. An Extension is installed for the whole platform and enabled per account. Code that walks resources generically asks whether a model’s manager has
with_read_permission_forbefore calling it, and treats a resource without one as readable.
A checklist for your own platform
The items are in rough order of payoff.
- Put ownership, permissions and caching in one abstract base model, and make every resource kind inherit from it.
- Make the owner a membership (a user in an account), not a user, and make names unique per owner.
- Derive read access from ownership with a few rules (the account, the platform) rather than storing grants, and return it as a
QuerySetso that it composes. - Keep write access a separate, stricter rule.
- Override every manager method that returns a queryset, so the permission methods survive chaining, and make it generic so that type checkers know the model.
- Give every row a string identity that’s unique across tables, and use it for budgets, charges, locks and urls instead of a foreign key to every table.
- Cache lookups by every name a resource has, join the owner chain into each one, and invalidate all of them on save.
- Validate in
save(), not just in forms and serializers. - Check budgets right before spending, never on read.
- Let people clone what they can read, so that sharing never has to mean editing someone else’s resource.
Closing thoughts
None of these pieces is unusual on its own. A foreign key to an owner, a unique constraint, a custom manager and a cache are all standard Django. What makes MetaDataWithOwnershipModel work is that it puts them in one class that every AI resource inherits, so the answer to “who owns this, who can see it, who pays for it, and where is it” is the same for a chatbot, a Secret and an api key. The next resource kind that Smarter adds gets all of it with one line, and its contributor can’t forget a permission filter that it inherited. ✨